Cluster Analysis Techniques from Professional Basketball Shooting Data Applied to Roulette Number Grouping Strategies
Blake Hansen · Aug 21, 2026
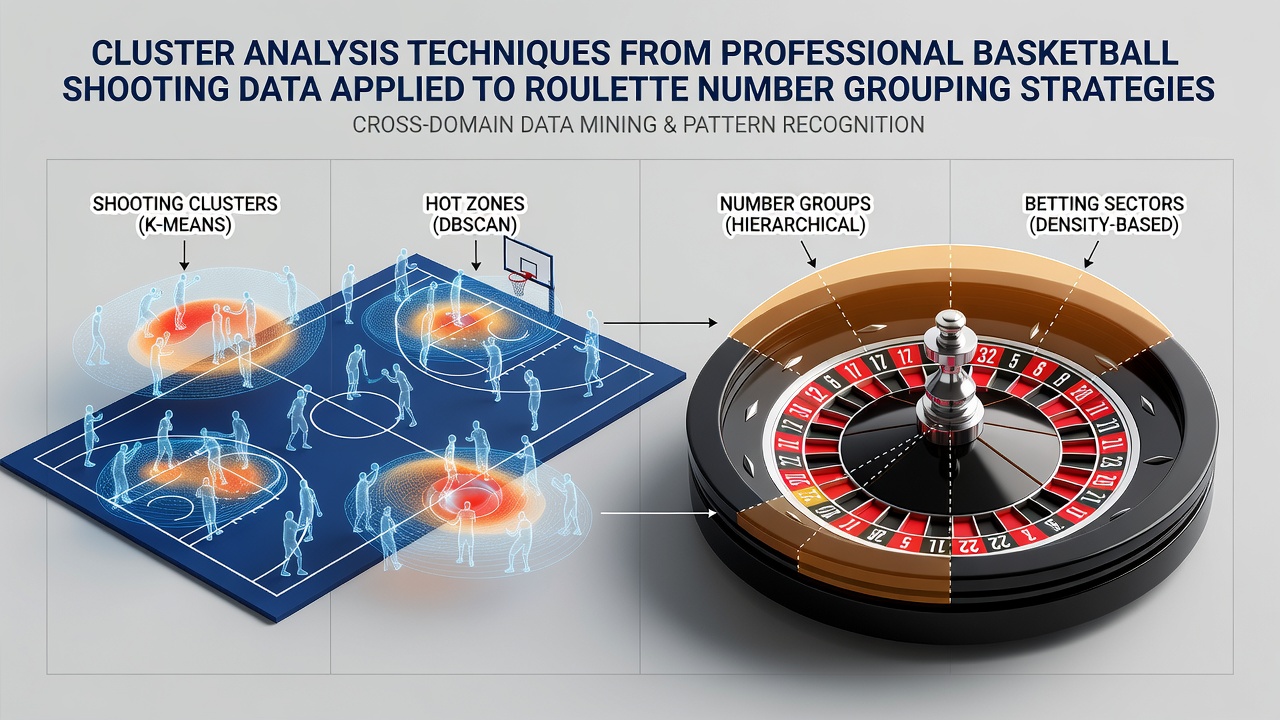
Cluster Analysis Techniques from Professional Basketball Shooting Data Applied to Roulette Number Grouping Strategies
Cluster analysis has gained traction in professional basketball as teams examine vast shooting datasets to identify patterns across court locations, player movements, and success rates, while researchers now explore parallel methods for grouping roulette numbers based on wheel sectors and historical frequency distributions. Data from the 2025-2026 NBA season shows analysts processing millions of shot attempts through algorithms that segment the court into micro-zones, revealing how certain clusters yield higher field goal percentages under specific defensive schemes.
Core Methods in Basketball Shot Clustering
K-means clustering remains a primary tool in basketball analytics because it partitions shooting locations into k groups that minimize variance within each cluster, and teams apply it to datasets containing coordinates, shot types, and contextual variables such as time remaining or defender proximity. Hierarchical clustering offers an alternative approach that builds dendrograms from individual shots upward, allowing analysts to observe how fine-grained zones merge into larger strategic groups, and this technique has proven useful when coaches review film from multiple games simultaneously. Researchers at academic institutions have documented these workflows in peer-reviewed studies that compare algorithm outputs against actual game results across several leagues.
Principal component analysis often precedes clustering steps to reduce dimensionality in high-volume tracking data, which includes variables like release angle, arc height, and distance from the basket, and the resulting components feed into grouping routines that highlight efficient versus inefficient shooting pockets. Observers note that these pipelines integrate with real-time systems during games, where updated clusters inform substitution patterns and play-calling adjustments as the season progresses into August 2026.
Mapping Concepts to Roulette Number Grouping
Analysts transfer the same clustering logic to roulette by treating wheel pockets as analogous to court zones and historical spin outcomes as equivalents to made or missed shots, which allows grouping of numbers that appear together more frequently within defined sectors. Euclidean distance calculations between pocket positions help form clusters around physical wheel segments, while frequency-based metrics incorporate long-term outcome tallies from regulated casino floors. Data from European gaming oversight bodies indicates that such groupings remain descriptive rather than predictive because each spin retains independent probability under standard wheel mechanics.
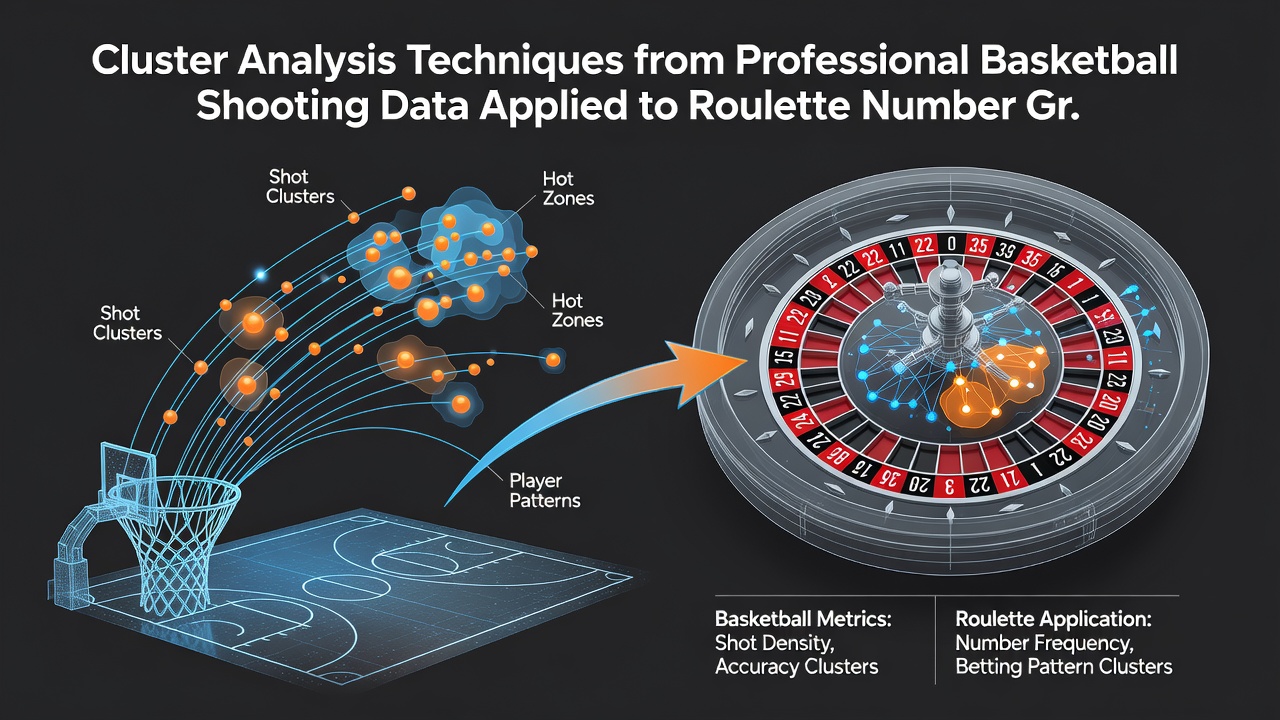
Hierarchical methods applied to roulette datasets produce tree structures that illustrate how single numbers combine into adjacent groups and then into broader color or dozen categories, and these outputs mirror the dendrograms generated from basketball shot charts. Software implementations normalize spin data by wheel bias measurements recorded during routine maintenance checks, ensuring clusters reflect both geometric layout and empirical distributions observed in controlled environments.
Comparative Data Processing Steps
Preprocessing pipelines for both domains begin with cleaning raw coordinate or outcome records, followed by feature scaling that equalizes the influence of spatial and temporal variables, and then proceed to algorithm selection based on dataset size. Validation techniques such as silhouette scoring assess cluster cohesion in basketball shooting data and receive parallel application to roulette number sets, where higher scores indicate tighter groupings around high-frequency sectors. Reports from the Nevada Gaming Control Board detail how similar statistical frameworks support internal auditing procedures without implying any alteration to game fairness standards.
Case examinations reveal one professional basketball franchise that reorganized its offensive sets after cluster maps identified underutilized mid-range pockets, and parallel exercises in casino analytics labs have produced visual overlays that segment roulette layouts into four or five primary groups for reporting purposes. These exercises draw from publicly available tracking repositories and anonymized spin logs released under regulatory transparency requirements.
Integration Challenges and Technical Considerations
Cross-domain application encounters differences in data velocity, because basketball tracking systems generate continuous streams during live play while roulette outcomes arrive at discrete intervals dictated by table pace, and engineers adjust sampling rates accordingly to maintain comparable cluster stability. Noise from tracking errors in sports footage requires filtering steps that parallel the handling of mechanical anomalies in physical wheels, and both fields employ outlier detection before final cluster assignment. Academic papers indexed through research databases document these adaptations across multiple continents, including contributions from Canadian statistical agencies that examine gaming data integrity protocols.
Computational resources scale with dataset volume, yet optimized libraries allow desktop-level hardware to process season-long basketball archives or multi-year roulette records within acceptable runtimes, and visualization layers convert cluster centroids into heatmaps that coaches and floor supervisors review during post-session debriefs.
Conclusion
Cluster analysis techniques refined through professional basketball shooting datasets supply structured frameworks that researchers adapt when examining roulette number groupings by sector and frequency, yet the underlying randomness of independent trials remains unchanged across both applications. Continued refinement of preprocessing, algorithm choice, and validation metrics supports clearer descriptive reporting in each domain as data collection expands through 2026 and beyond.